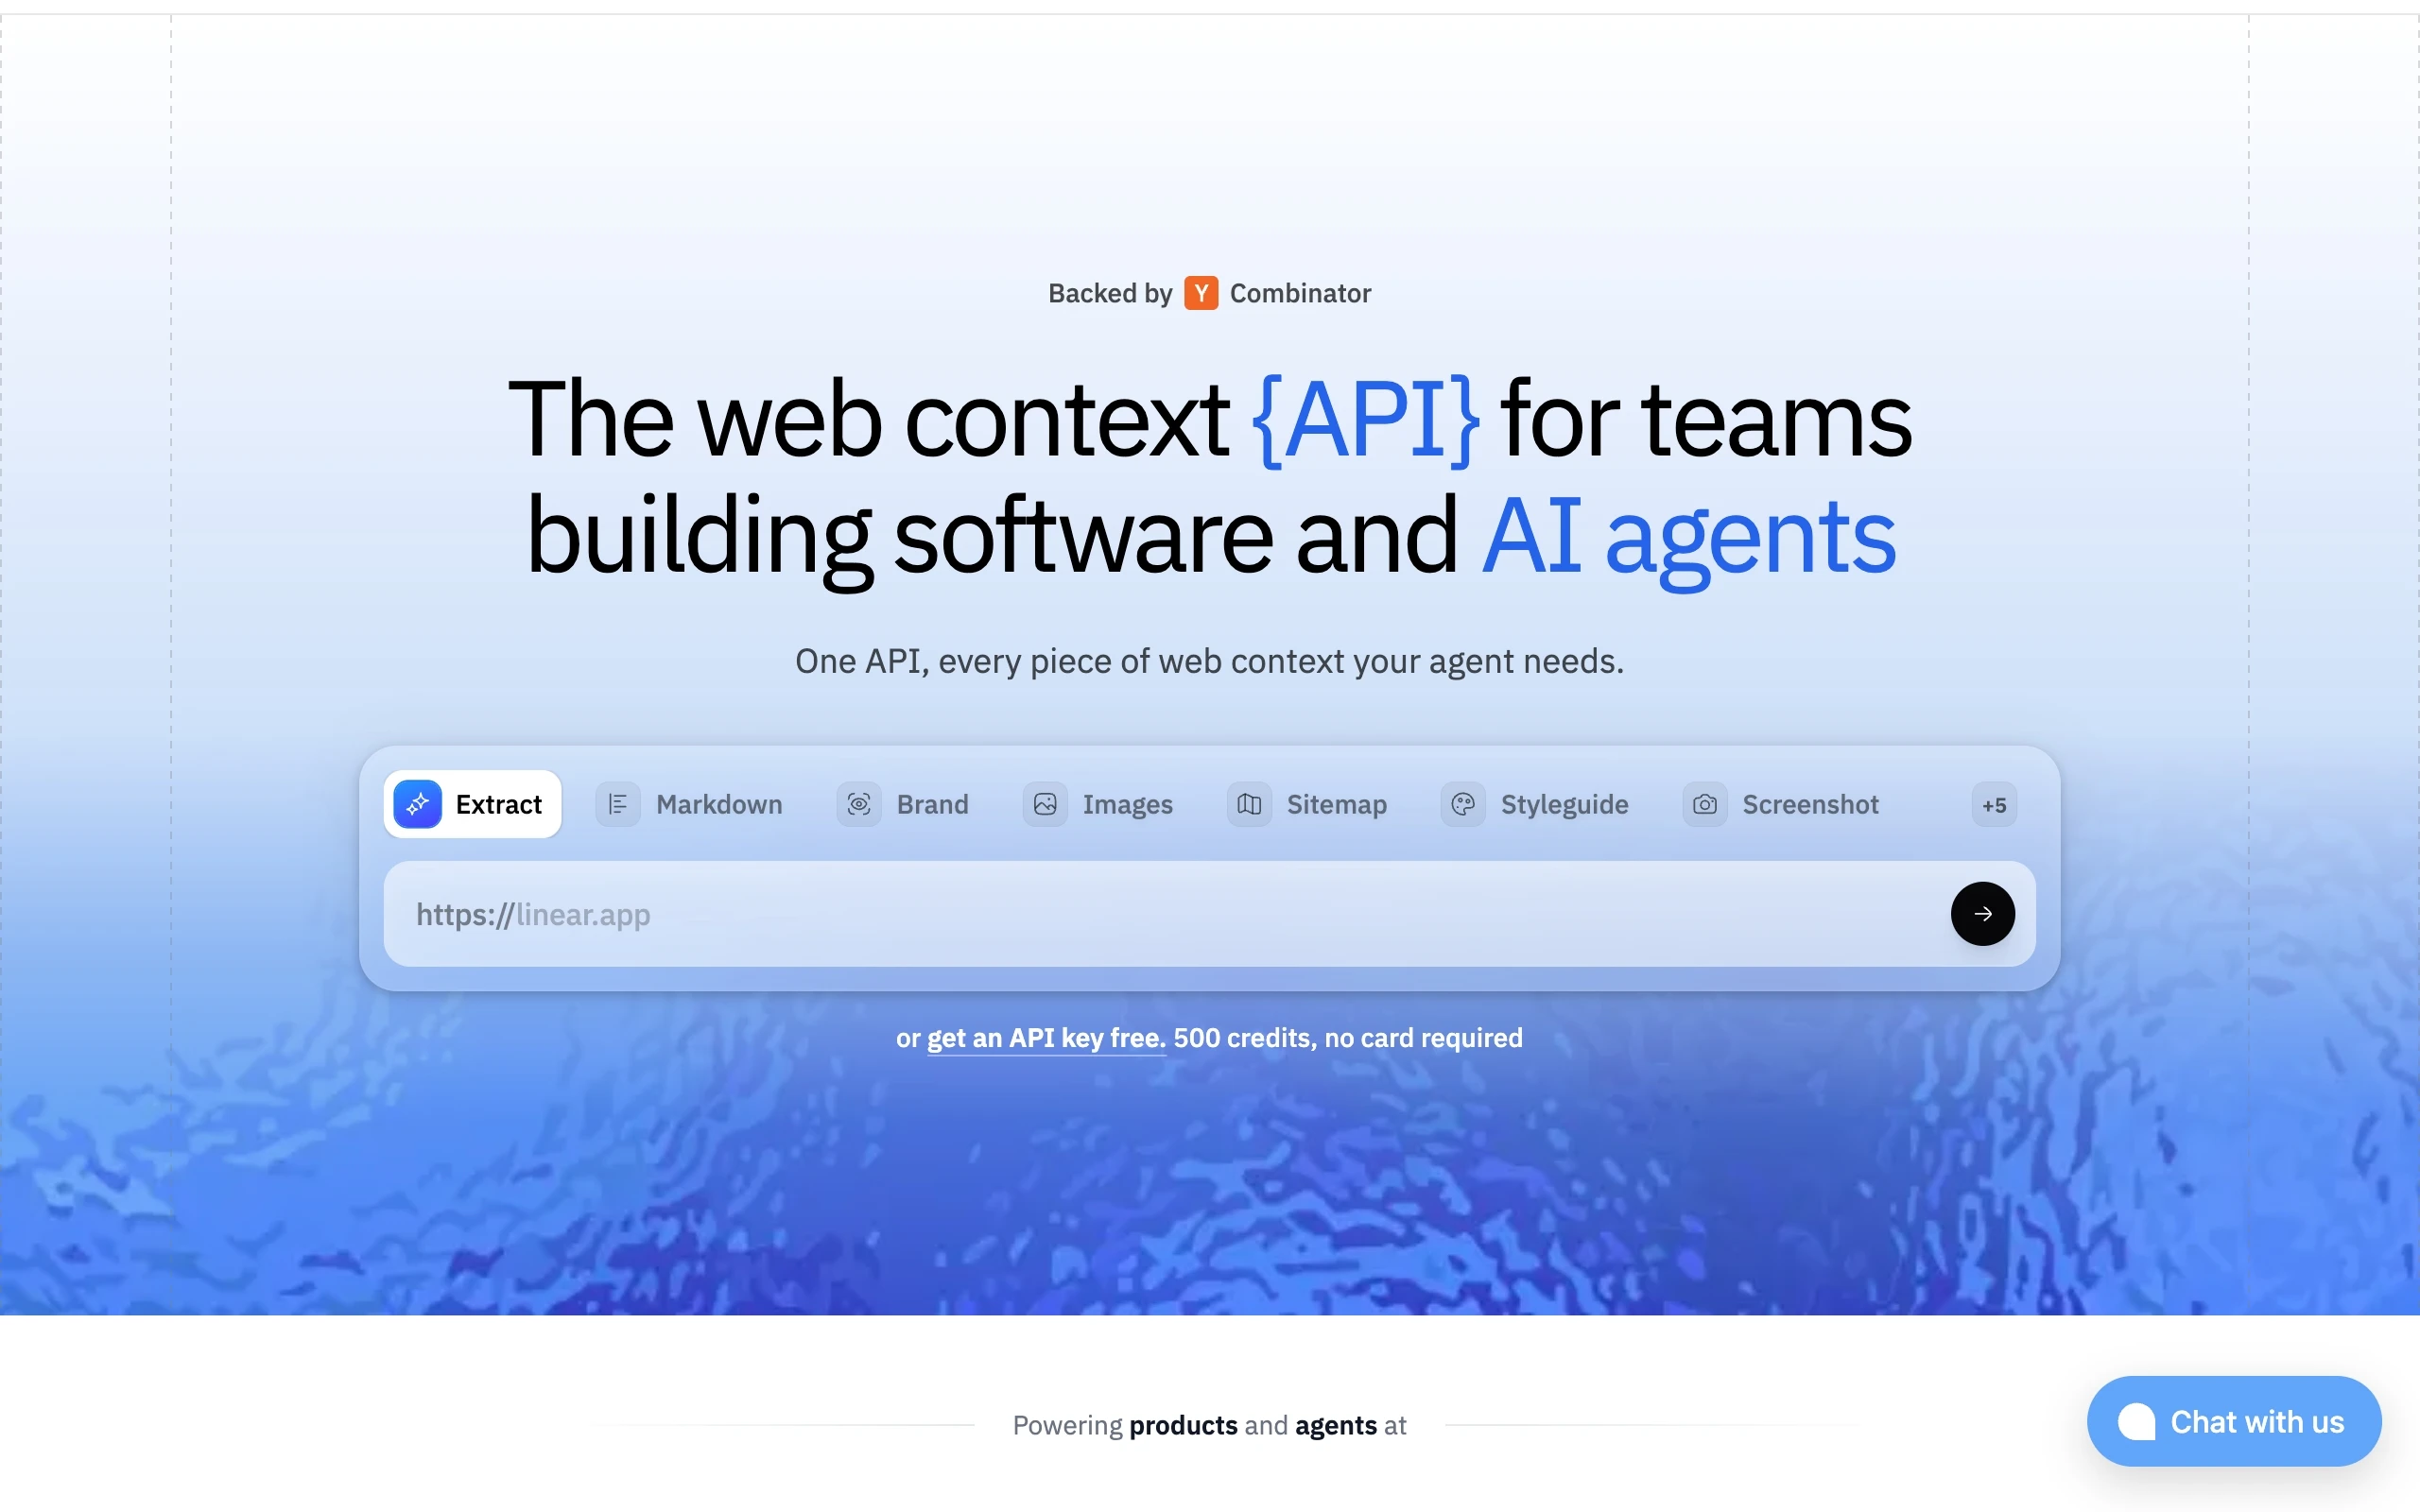
Single API to scrape, enrich, and deliver web data to AI agents.
What it does
Scrapes URLs and crawls websites directly into token-efficient markdown or clean HTML for AI LLM ingestion.
Extracts complete brand styleguides including logos, exact hex color schemes, typography, and company firmographics.
Discovers page URL structures and extracts clean data across full sites via native sitemap crawlers.
Offers direct Logo Link and prefetch endpoints to render company brand assets rapidly without API credit exhaustion.
Why it works
Built-in anti-bot bypass and JavaScript rendering eliminate proxy management overhead for engineering teams.
Clean markdown conversion reduces token consumption when feeding live web results into LLM context windows.
Typed SDKs for TypeScript, Python, Go, Ruby, and PHP enable rapid drop-in integration in under 10 minutes.
Dual-quota architecture separates low-latency direct logo asset fetching from complex web scraping queries.
Single API to scrape, enrich, and deliver web data to AI agents.
Overview
Context.dev is an AI-native web scraping and brand intelligence API designed to supply real-time structured data to AI agents and automated application workflows. It converts raw HTML into clean markdown, extracts structured site visual identities, crawls sitemaps, and performs deep brand enrichment through a single REST interface. By handling anti-bot stealth and proxy infrastructure natively, Context.dev provides reliable, agent-ready context without maintaining custom crawler pipelines.
Founded year:2025
Founder:Yahia Bakour
Team size:1 or 2-10
Popularity:Trusted by over 5,000 businesses and powering AI agents for companies like Mintlify, Klarna, and Daily.dev.
HQ:San Francisco, California, United States
Status:Active
Funding status:Funded
Customer type:B2B
Funding:Funded (Y Combinator S26)
Pricing:Freemium
Tech stack:TypeScript, Python, Go, Node.js, Vercel, REST API
Platform:Web
Integrations:TypeScript SDK, Python SDK, Go SDK, Ruby SDK, PHP SDK, n8n, REST API
What it does
Scrapes URLs and crawls websites directly into token-efficient markdown or clean HTML for AI LLM ingestion.
Extracts complete brand styleguides including logos, exact hex color schemes, typography, and company firmographics.
Discovers page URL structures and extracts clean data across full sites via native sitemap crawlers.
Offers direct Logo Link and prefetch endpoints to render company brand assets rapidly without API credit exhaustion.
Who it's for
AI Agent Developers & Software Engineers
B2B SaaS Onboarding & CRM Platforms
Lead Generation & Market Intelligence Teams
Automation & Workflow Engineers
Why it works
Built-in anti-bot bypass and JavaScript rendering eliminate proxy management overhead for engineering teams.
Clean markdown conversion reduces token consumption when feeding live web results into LLM context windows.
Typed SDKs for TypeScript, Python, Go, Ruby, and PHP enable rapid drop-in integration in under 10 minutes.
Dual-quota architecture separates low-latency direct logo asset fetching from complex web scraping queries.
Founder story
Context.dev was founded in 2025 by Yahia Bakour in San Francisco. Having previously worked as a Principal SWE Manager at Sunrun, an Amazon SDE2 on retail checkout systems, and co-founding StockAlarm.io, Bakour experienced firsthand how fragile scraping pipelines crippled AI agents. Backed by Y Combinator, he built Context.dev to supply LLMs with clean, realtime web context through a single developer API.
Alternatives
Comparison overview
Context.dev combines markdown web scraping with typed company brand intelligence and styleguide extraction in a single API, whereas alternative tools like Firecrawl focus primarily on web-to-markdown conversion.
Context.dev provides dedicated Logo Link endpoints without rate limits alongside metered scraping credits, while general proxy scrapers bill uniformly per HTML request.