Loading SaaS profile...
Loading SaaS profile...
AI voice typing and dictation software for Mac and Windows.
Turns rough spoken ideas into polished, ready-to-use writing across any application. Captures on-screen context so users can point at charts or code and ask questions by voice. Executes voice-driven workflows for rewriting, translation, and scheduling tasks. Reads screen content aloud with a listen mode for hands-free consumption.
Built on in-house trained multimodal models rather than relying on a cascade of basic transcription APIs. Captures context directly from the screen, making it highly accurate for coding and data-heavy workflows. Eliminates context switching by allowing users to speak commands natively across macOS and Windows. Supports over 100 languages, providing global accessibility for complex voice-to-text operations.
Category: Productivity
Team Size: 2-10
Visit Website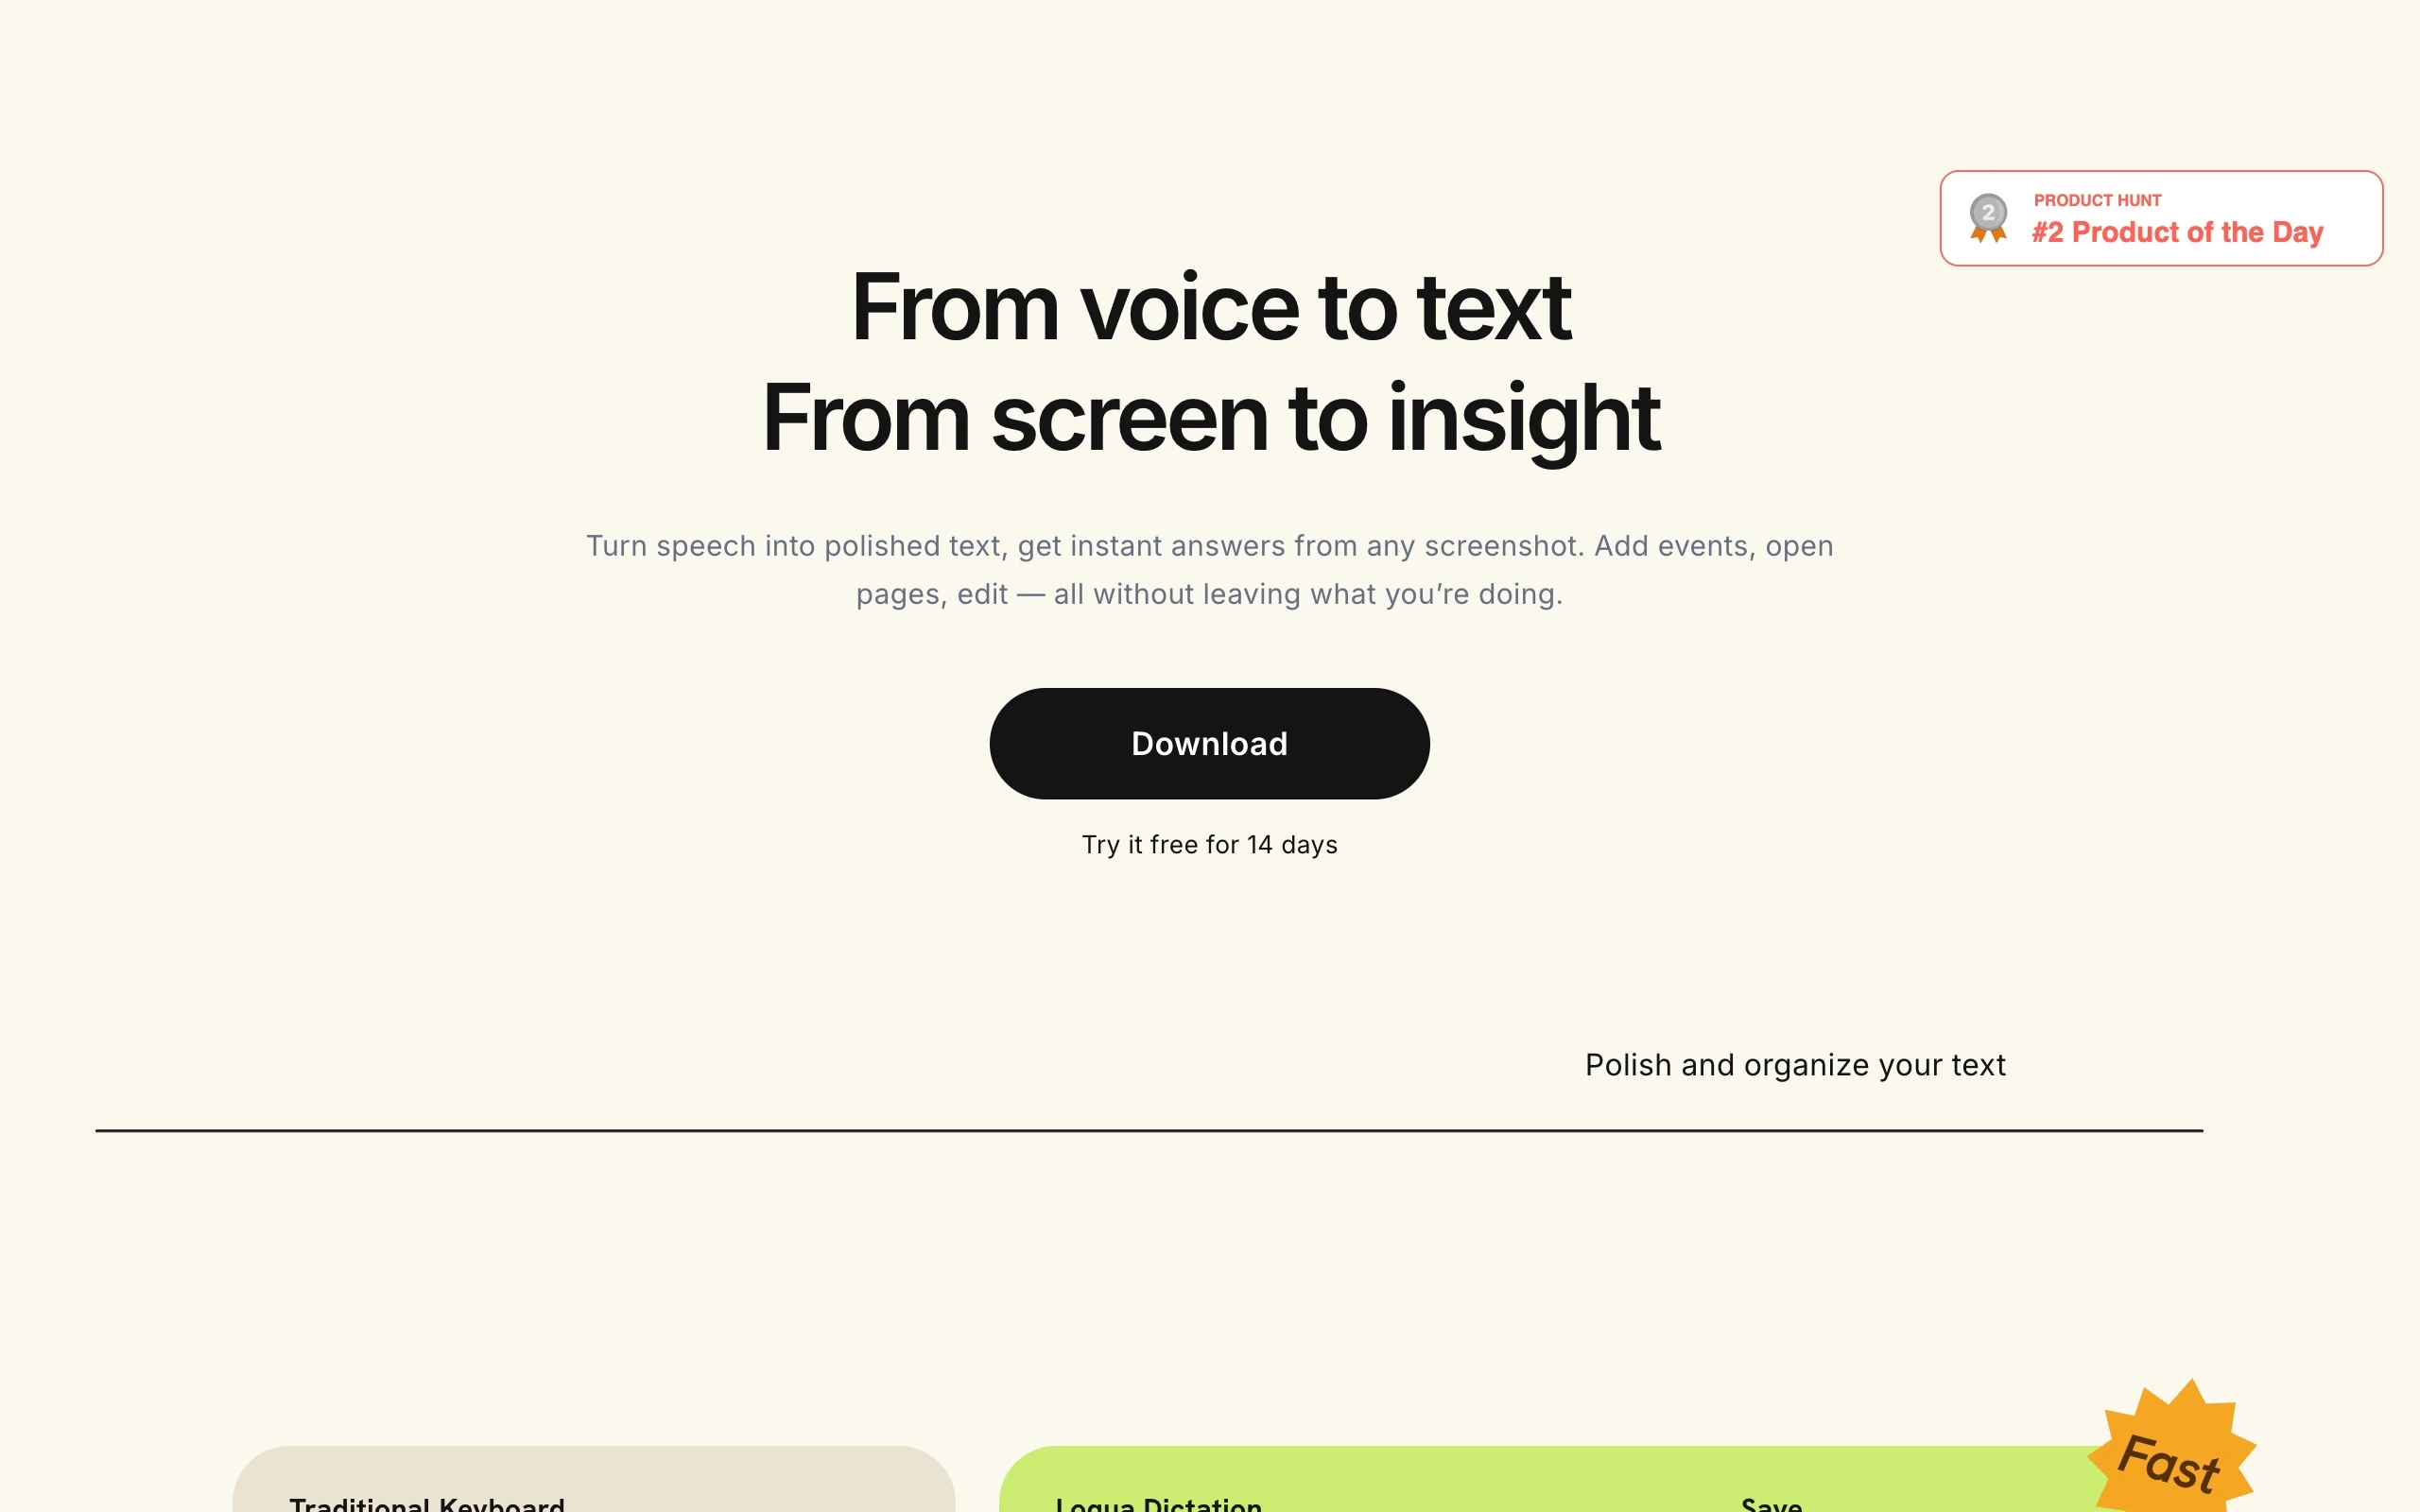
Loqua is an AI-powered voice typing and dictation tool for Mac and Windows that turns spoken thoughts into ready-to-use writing. It goes beyond simple transcription by utilizing custom multimodal models that understand both voice and on-screen context. Users can execute voice-driven workflows for tasks like rewriting, translation, scheduling, and coding without context switching.
Loqua was founded by Joshua Zhou, a speech and LLM research scientist who grew frustrated with legacy dictation tools that failed to understand meaning or context. Realizing that existing solutions were merely API wrappers, his team built custom multimodal models to create a voice interface that both hears and sees.