Loading SaaS profile...
Loading SaaS profile...
Open-source microdata cataloging system for researchers and archives.
Document, store, and publish rich study-level metadata, data files, and variables using DDI standards. Provide full-text keyword searches and filters for browsing large census and survey datasets. Manage user accounts, data access requests, and restricted downloads via an administrative interface. Expose REST APIs for seamless programmatic searching and browsing of cataloged microdata archives.
Leverages open-source architecture lowering deployment barriers for national and international research organizations. Implements DDI and Dublin Core XML international standards ensuring standardized data documentation and exchange. Features built-in REST API support allowing flexible data integration and automated catalog querying. Provides a robust admin interface and access request workflow to streamline controlled microdata distribution.
Category: Utilities & System Tools
Team Size: 100+
Visit Website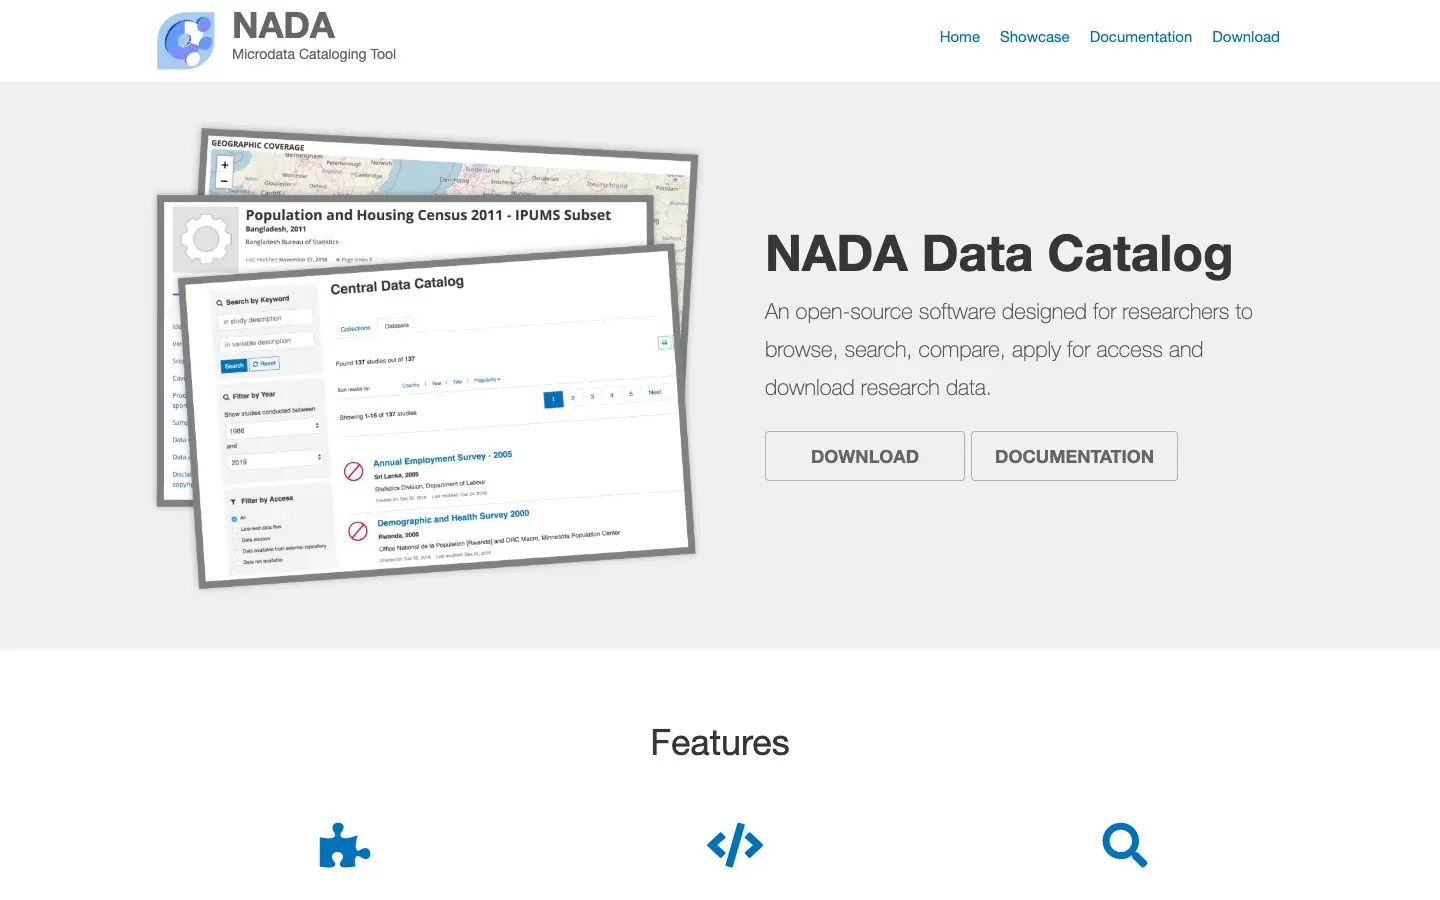
NADA is an open-source microdata cataloging system developed by the International Household Survey Network (IHSN). It serves as an online portal for researchers to browse, search, compare, and download census and survey information. The application utilizes international metadata standards like DDI to ensure seamless data discovery. Organizations worldwide use NADA to manage, document, and safely publish institutional microdata archives.
NADA was originally developed by the International Household Survey Network (IHSN), hosted by the World Bank, to support the establishment of national survey data archives. Released as an open-source tool, it solves the challenge of properly cataloging, discovering, and disseminating complex microdata to researchers globally.