Loading SaaS profile...
Loading SaaS profile...
Turns natural language prompts into production-optimized AI inference APIs.
Generates custom CUDA and Triton kernels for Hugging Face models using agentic optimization loops. Benchmarks serving engines and GPU instances to establish verified latency and throughput metrics. Deploys OpenAI-compatible endpoints supporting streaming, tool use, embeddings, and vision-language tasks. Exports complete deployment kits including Dockerfiles and configuration files for self-hosted execution.
Agentic kernel synthesis removes manual vLLM configuration and low-level CUDA tuning requirements. Pay-per-million token pricing with scale-to-zero capabilities prevents idle server compute expenses. Zero lock-in architecture allows exporting full deployment kits directly to private cloud accounts. Built-in benchmark receipts provide verified before-and-after performance validation on real hardware.
Category: AI & Automation
Team Size: 2-10
Visit Website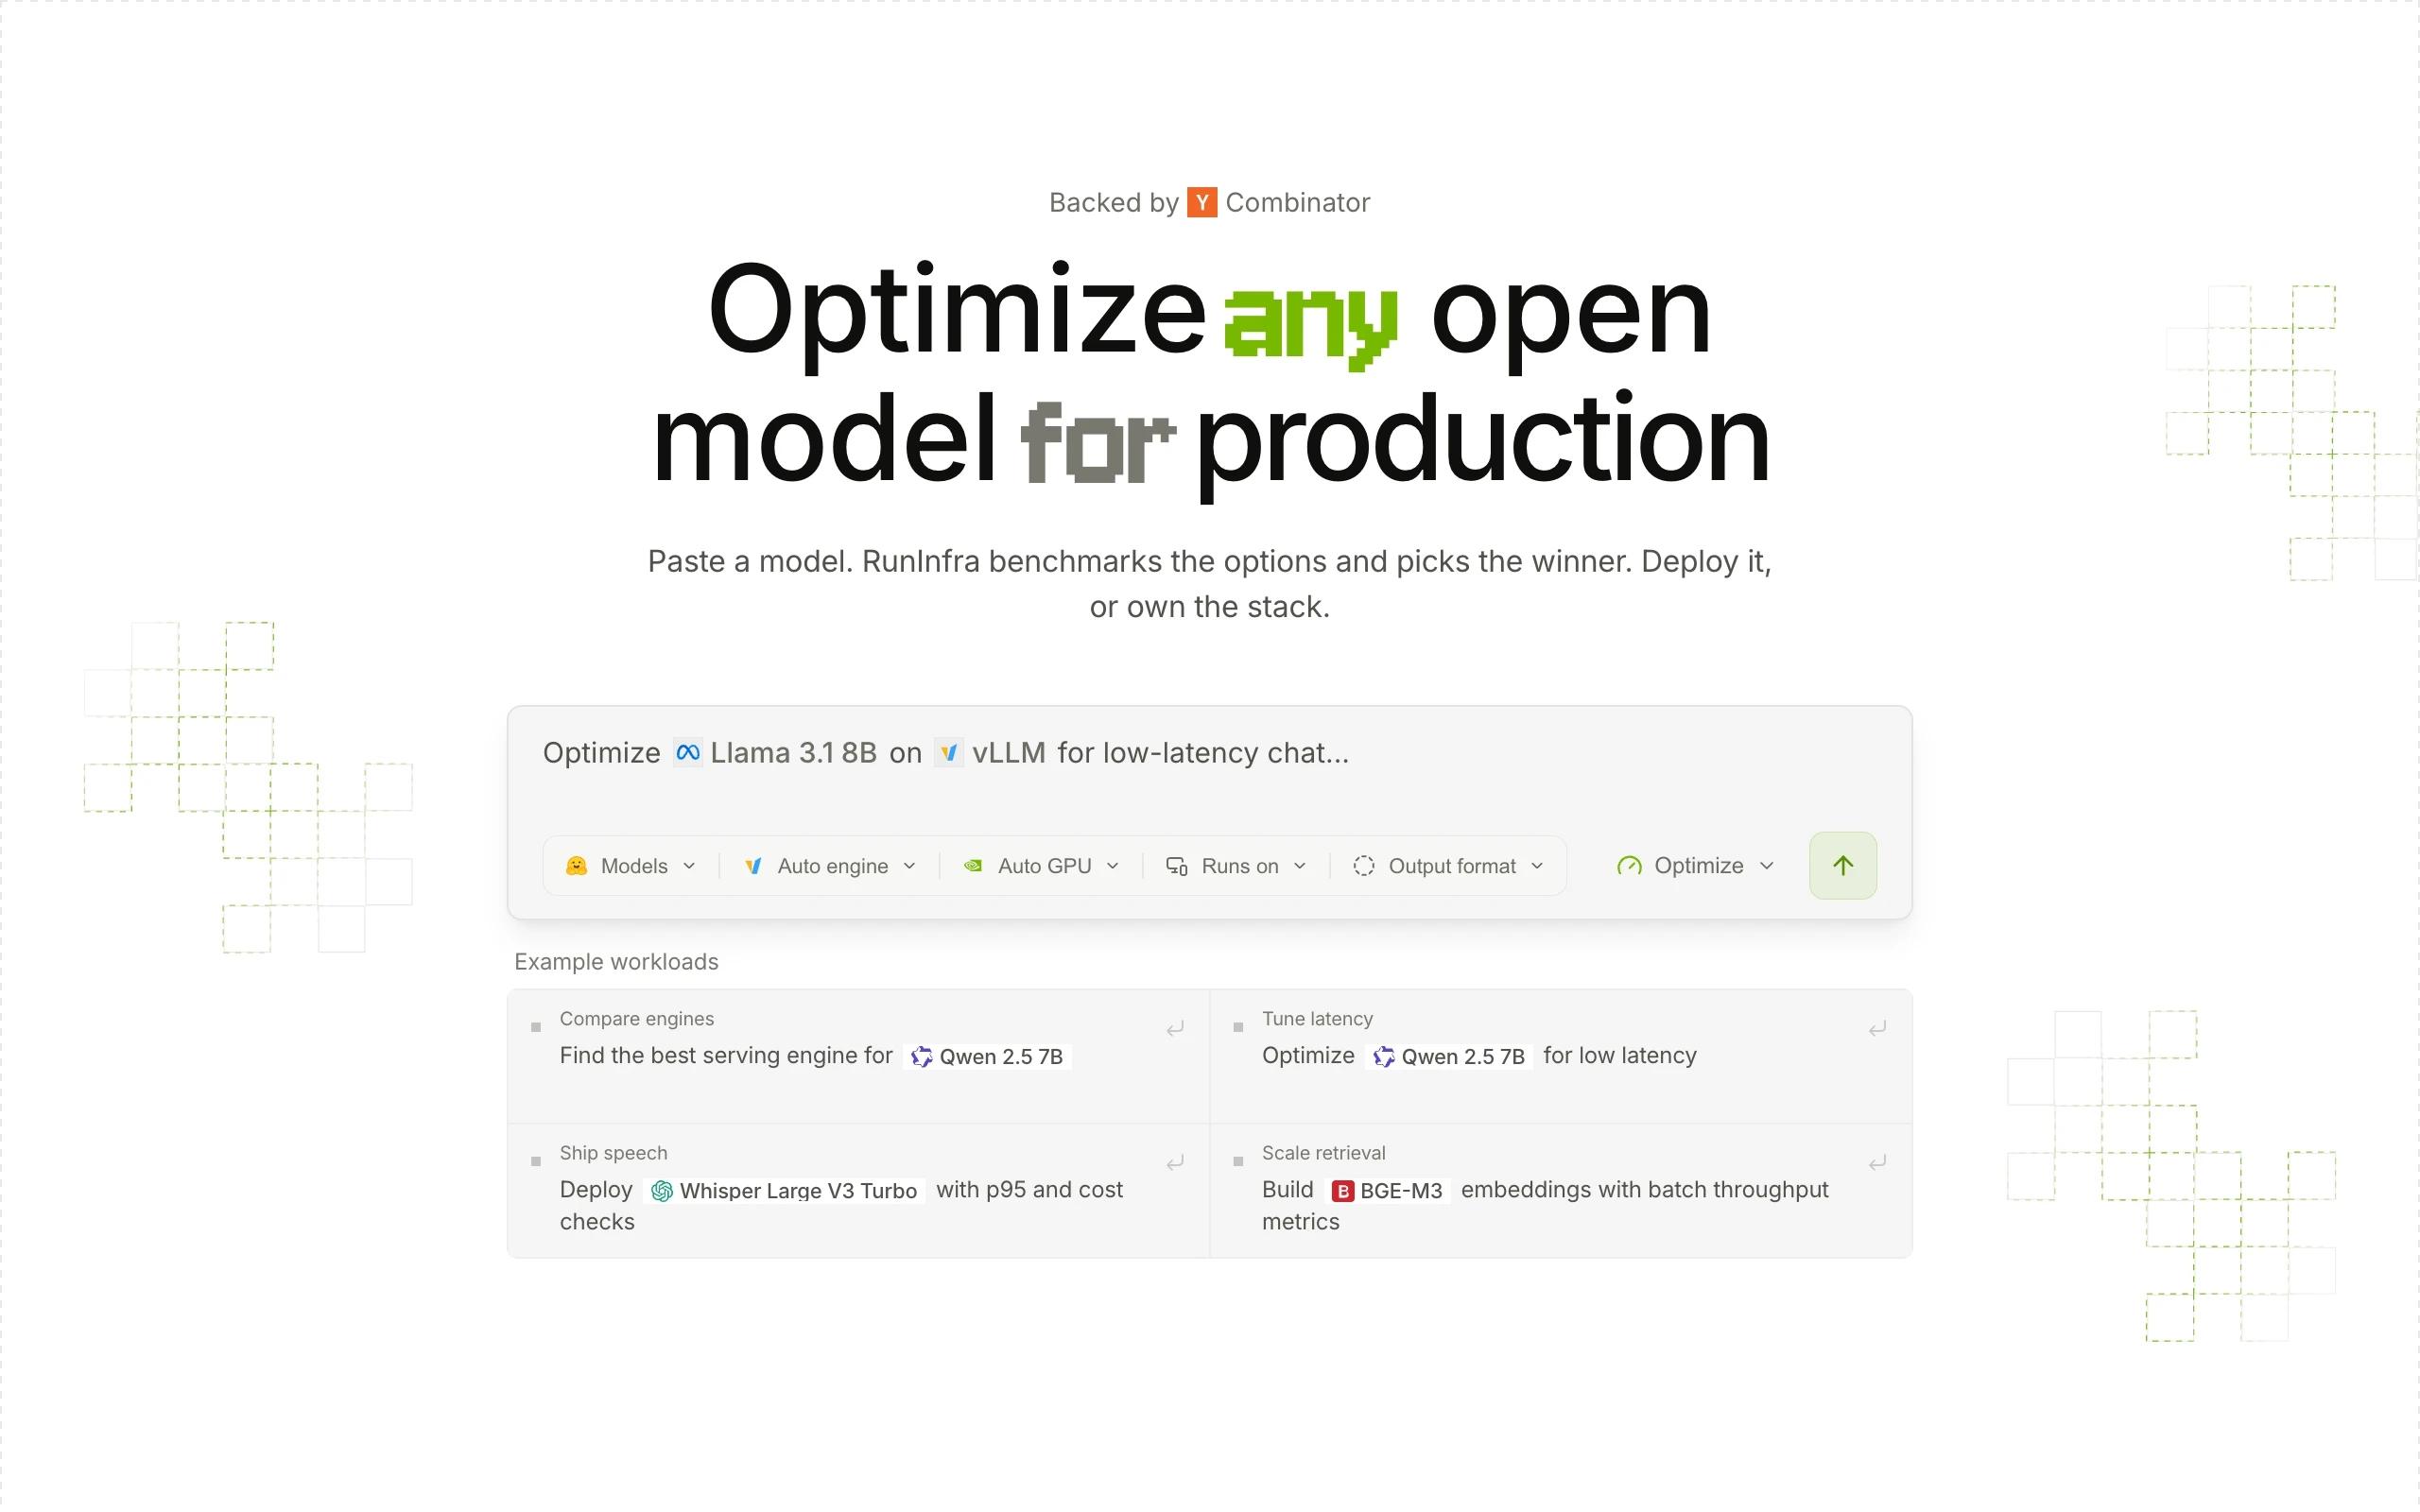
RunInfra is an AI-powered GPU infrastructure and model deployment platform developed by RightNow AI. By describing desired inference workloads in plain text, the platform's AI agent selects compatible open-source models, benchmarks candidate serving engines like vLLM and SGLang on physical GPUs, and generates custom CUDA kernels using its Forge agent. The resulting OpenAI-compatible API endpoint can be deployed on managed serverless infrastructure with scale-to-zero pricing or exported to self-hosted clouds.
RunInfra was built by Jaber Jaber and Osama Jaber under the RightNow AI research lab in 2026. Frustrated by the weeks of manual work required to select GPUs, benchmark serving engines like vLLM, and write CUDA kernels for open-source AI models, the founders developed an autonomous agent harness to automate low-level hardware optimization through plain English commands.