Loading SaaS profile...
Loading SaaS profile...
Turn documents and articles into editable multi-voice audio.
Parses PDFs, documents, markdown notes, and web articles to generate structured outlines and natural spoken scripts. Provides editable script segments allowing users to refine text and customize dialogue before audio synthesis. Assigns distinct multi-voice speaker models to different parts of the content for engaging listening flows. Exports final multi-voice audio files suitable for offline learning, study notes, and research review.
Transfers opaque text-to-speech workflows into transparent, editable script structures prior to voice synthesis. Turns passive saved reading lists into active, high-retention audio content for commutes and workouts. Delivers multi-voice persona customization to make long-form technical papers sound like natural discussions. Offers flexible processing models suitable for academic research papers, news articles, and personal notes.
Category: AI & Automation
Team Size: 1
Visit Website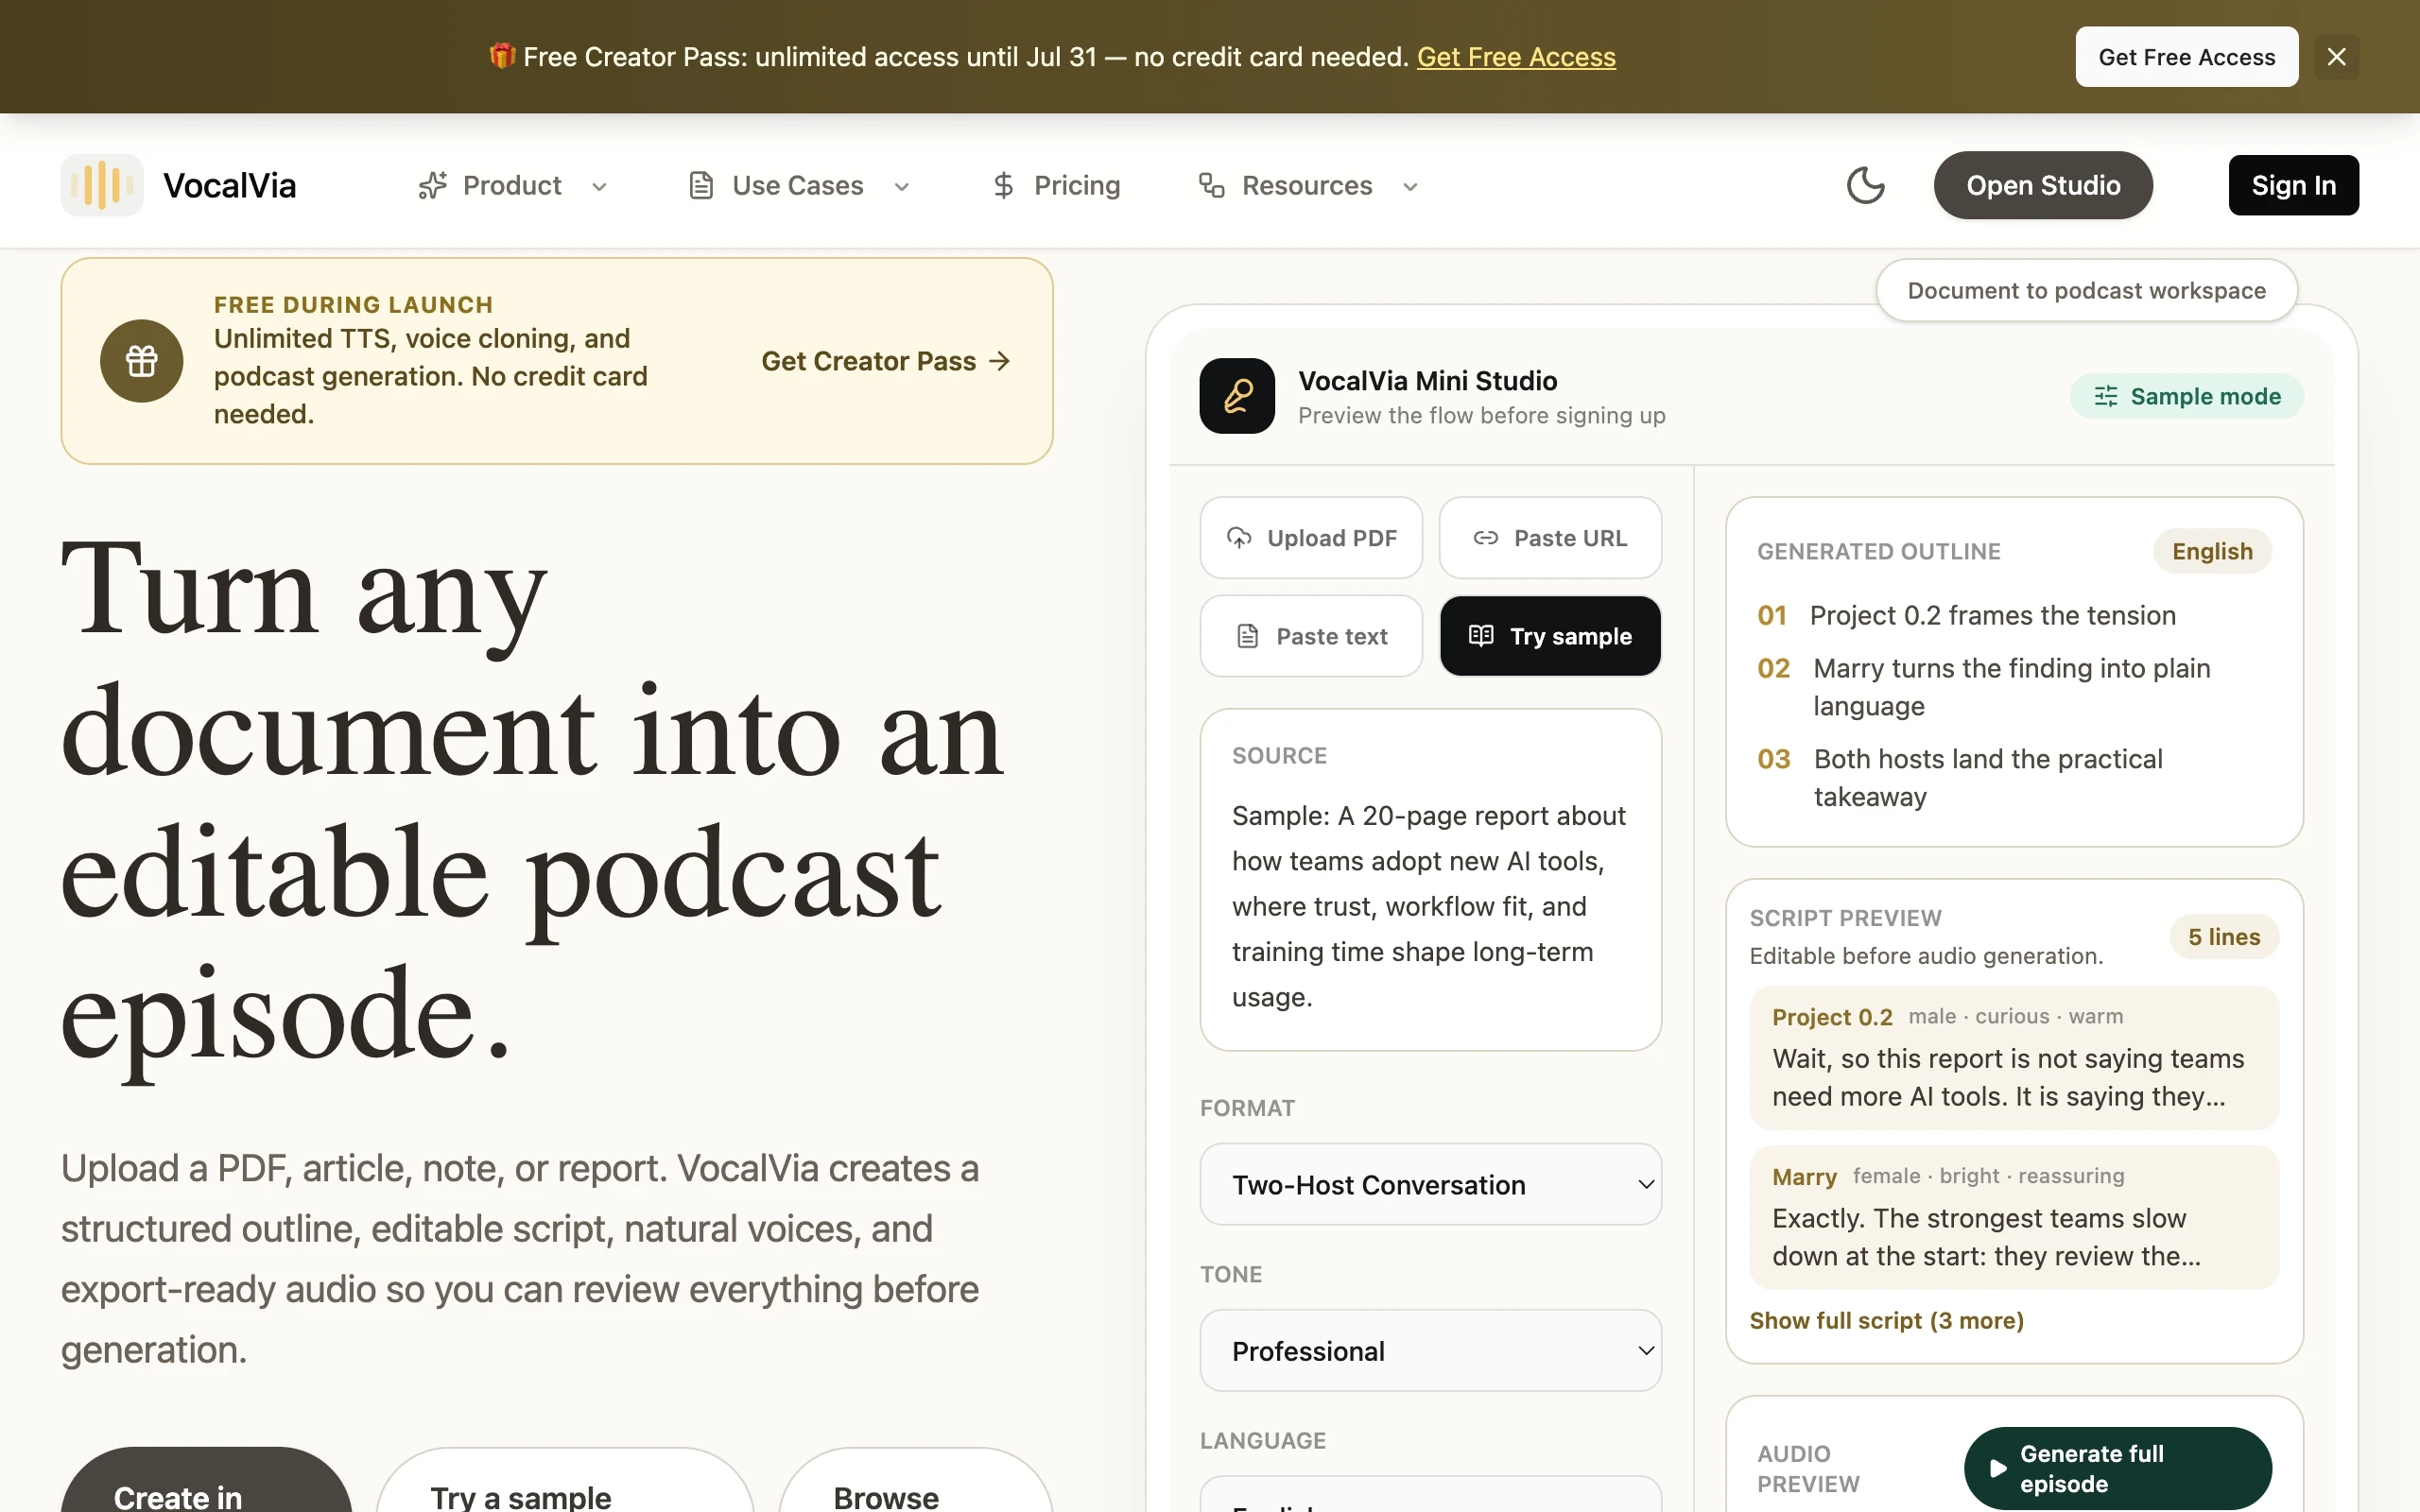
VocalVia is an advanced AI audio platform designed to transform PDFs, Word files, Markdown notes, web articles, and raw text into structured outlines, editable podcast scripts, and natural multi-voice audio. It solves the challenge of saved reading overload by converting complex content into screen-free listening formats. Users can inspect outlines, edit dialogue segments, assign distinct speaker voices, and export professional audio outputs.
VocalVia was created by developer Zoey after noticing how many useful PDFs and articles were continually saved but never actually read. Frustrated by opaque document-to-speech tools that lacked customization, the founder built a practical workflow that converts text into inspectable outlines, editable multi-voice scripts, and clear audio.